AI benchmarks are becoming increasingly central to policy debates. But much of the value of these benchmarks depends on how they are built: what they measure, who develops and runs them, and how quickly they evolve alongside the models they evaluate.
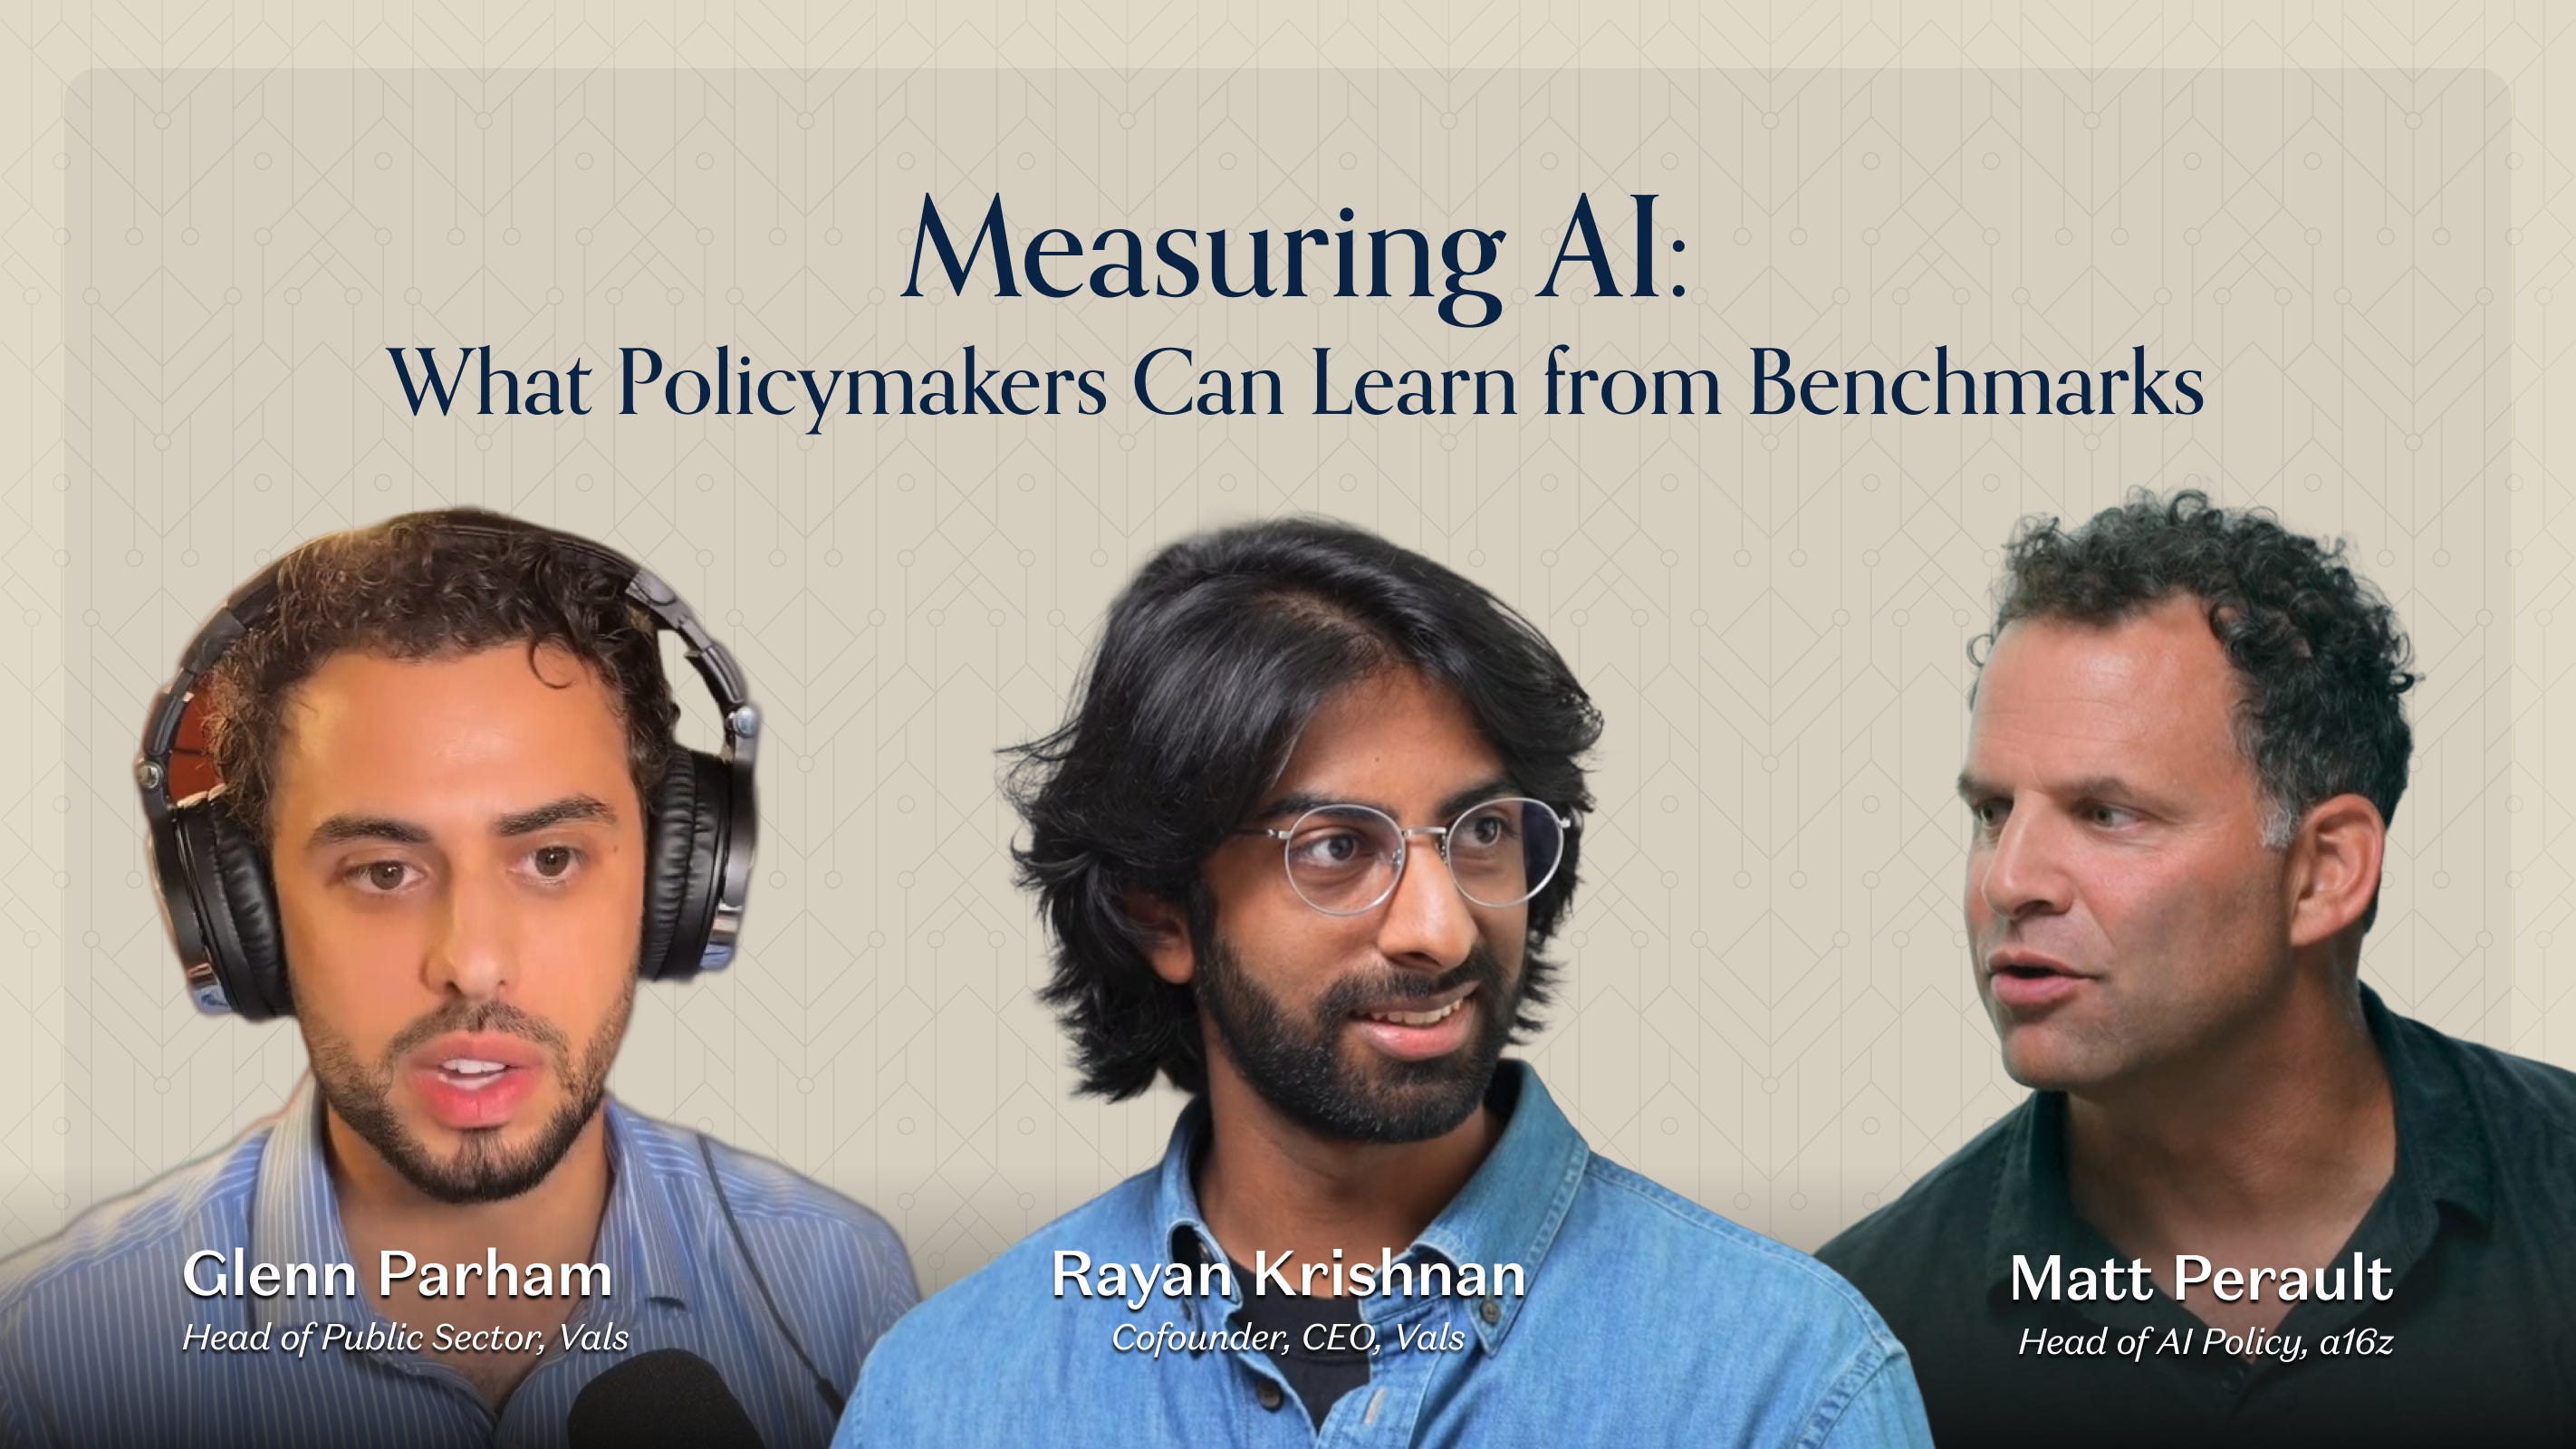
In this episode, Matt Perault speaks with Rayan Krishnan, cofounder and CEO of Vals, and Glenn Parham, head of public sector, about their work building AI evaluation tools and partnerships for industry and government. They discuss why static tests quickly become obsolete, why credible evaluations require deep domain expertise and independent testing, and how a growing market of evaluators is moving the field beyond “evaluations by vibes” toward more rigorous, data-driven evidence for policymakers.
Topics covered:
00:00: Intro
02:00: What is Vals?
05:00: Keeping benchmarks current
08:00: New strides in AI evaluation
11:00: Measuring AI’s cyber capabilities
14:00: Why government needs independent evaluation
21:00: The growing market for AI benchmarks
26:00: What benchmarks can—and cannot—measure
29:00: Building trust in AI benchmarks
35:00: Why AI performance varies across domains and tasks
37:00: Bringing AI evaluation to government
41:00: From “evaluations by vibes” to better evidence
Resources:
Subscribe to the a16z AI Policy Brief: https://a16zpolicy.substack.com/
Follow Matt Perault on X: https://x.com/MattPerault
Follow Rayan Krishnan on X: https://x.com/RayanKrishnan
Follow Glenn Parham on X: https://x.com/glenn__parham
Follow Vals.ai on X: https://x.com/ValsAI
The content here is for informational purposes only, should not be taken as legal, business, tax, or investment advice or be used to evaluate any investment or security, and is not directed at any investors or potential investors in any a16z fund. Please note that a16z and its affiliates may maintain investments in the companies discussed in this podcast. For more details, including a link to our investments, please see a16z.com/disclosures.