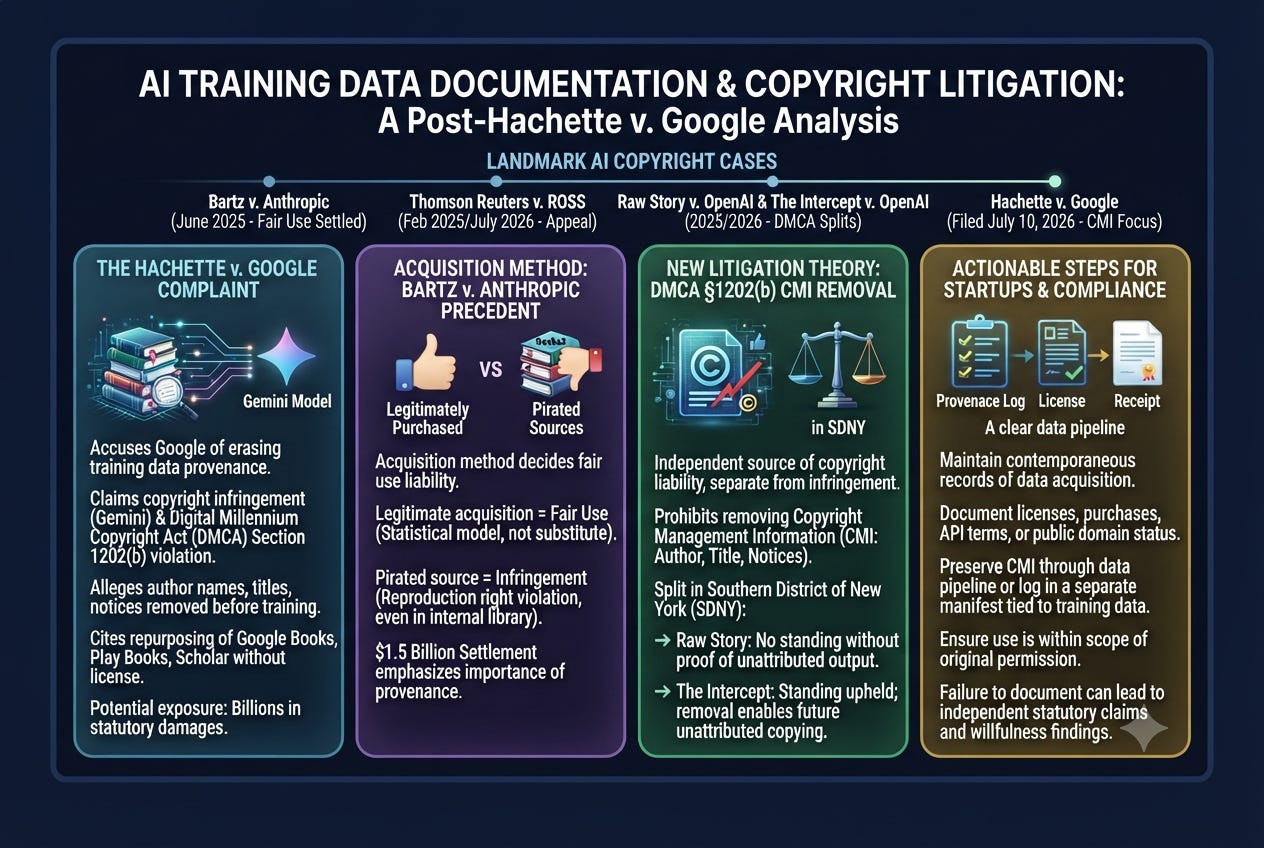
Hachette Book Group v. Google LLC, filed July 10, 2026 in the Southern District of New York, alleges Google stripped author names and titles from books before training Gemini. That single allegation is reshaping what training data documentation a startup needs to keep. The complaint does not ask whether training a model on a book is lawful. It asks whether erasing the record of where the book came from is its own separate violation, regardless of the answer to the first question.
Hachette Book Group, Cengage Learning, and Elsevier brought the case, joined by novelist Scott Turow and his company S.C.R.I.B.E. The complaint traces the Gemini training corpus to three channels: books supplied to Google Books for search and snippet display, books and journal articles uploaded to Google Play Books and Google Scholar for sale and access, and a separate stream the complaint says came from pirate sites and paywalled subscription libraries by way of the Common Crawl web dataset. The first two channels support a conventional infringement claim, that content handed over for one purpose was repurposed for another without a separate license. The third channel supports something narrower and, for a company building its own model, more instructive: a claim under Section 1202 of the Digital Millennium Copyright Act, which punishes removing or altering copyright management information with knowledge that doing so will conceal or facilitate infringement.
That statute has stayed largely in the background of AI litigation for two years, and it just moved to the foreground. Judge William Alsup’s 2025 order in Bartz v. Anthropic already established that fair use exposure turns on acquisition method as much as training method: training on legitimately purchased books was protected, training on a permanent library built from pirated copies was not, and the difference cost Anthropic $1.5 billion in a September 2025 settlement. Hachette borrows that logic and applies it one layer deeper. It asks more than how Google acquired the books. It asks whether Google then erased the evidence of how it acquired them.
Section 1202 claims have had an uneven run in federal court, and the unevenness is the story worth watching. In Raw Story Media v. OpenAI, Judge Colleen McMahon dismissed a metadata removal claim in 2025 because the plaintiffs could not show ChatGPT had ever actually output their stripped articles to a user, calling that risk remote. In The Intercept Media v. OpenAI, Judge Jed Rakoff looked at nearly identical facts and reached the opposite conclusion, holding that a copyright injury does not require publication to a third party and accepting a theory that stripped metadata creates its own downstream risk. Two judges on the same court, reading the same statute, arrived at opposite answers within months of each other.
Then, on September 16, 2026, the Ninth Circuit narrowed the theory in Doe v. GitHub, holding that an AI system’s output lacking attribution is not, by itself, proof that copyright management information was removed. The court wanted proof that the information was stripped from an existing copy of the work, not merely absent from a generated response. But the panel pointedly declined to decide the one question closest to Hachette’s complaint: whether removing an author’s name and a book’s title before feeding the text into a training run violates the statute at all. The plaintiffs in that case had not preserved the argument, so the Ninth Circuit left it on the table. Hachette picked it up three months later, in a different circuit, against a different defendant, with a complaint built specifically around it.
In three decades of reviewing data license agreements for technology companies, the clause that gets the least attention at signing is almost always the one that matters most two years later: the one describing exactly where the data came from and under what terms. Founders treat it as boilerplate. Litigators treat it as the whole case. Hachette v. Google is the clearest evidence yet that the second group has the better read. A startup that can produce, for every corpus in its training pipeline, a contemporaneous record showing how the text was acquired, whether that use stayed within the scope of the license or terms of service it was acquired under, and whether the author and title metadata embedded in the source was preserved or independently logged, is answering the Hachette theory before a plaintiff’s lawyer ever gets to ask the question. A startup that instead treats data provenance as something to reconstruct after a demand letter arrives is building the exact fact pattern that turned a training run into a billion dollar settlement for Anthropic and a live circuit question for Google.
None of this changes the underlying fair use analysis, which is still working its way through the courts and will get its first appellate answer when the Third Circuit rules on Thomson Reuters v. Ross Intelligence, expected before the end of 2026. What it changes is the cost of doing nothing. A company can lose on fair use with perfect records or win on fair use with none, but a metadata removal claim under Section 1202 travels on its own track, with its own damages formula, and Hachette has shown exactly how to plead it against a company far larger than any startup reading this. The next piece in this sequence looks at the Third Circuit’s decision in Ross v. Thomson Reuters once it lands, and at what a ruling on that purpose and character question from a federal appeals court, the first of its kind, will mean for every company that has been building a model on the assumption that training itself is the only legal question that matters.
Interested in analysis about the intersection of tech, policy and the law? Check out my Substack channel. https://theinnovationattorney.substack.com/