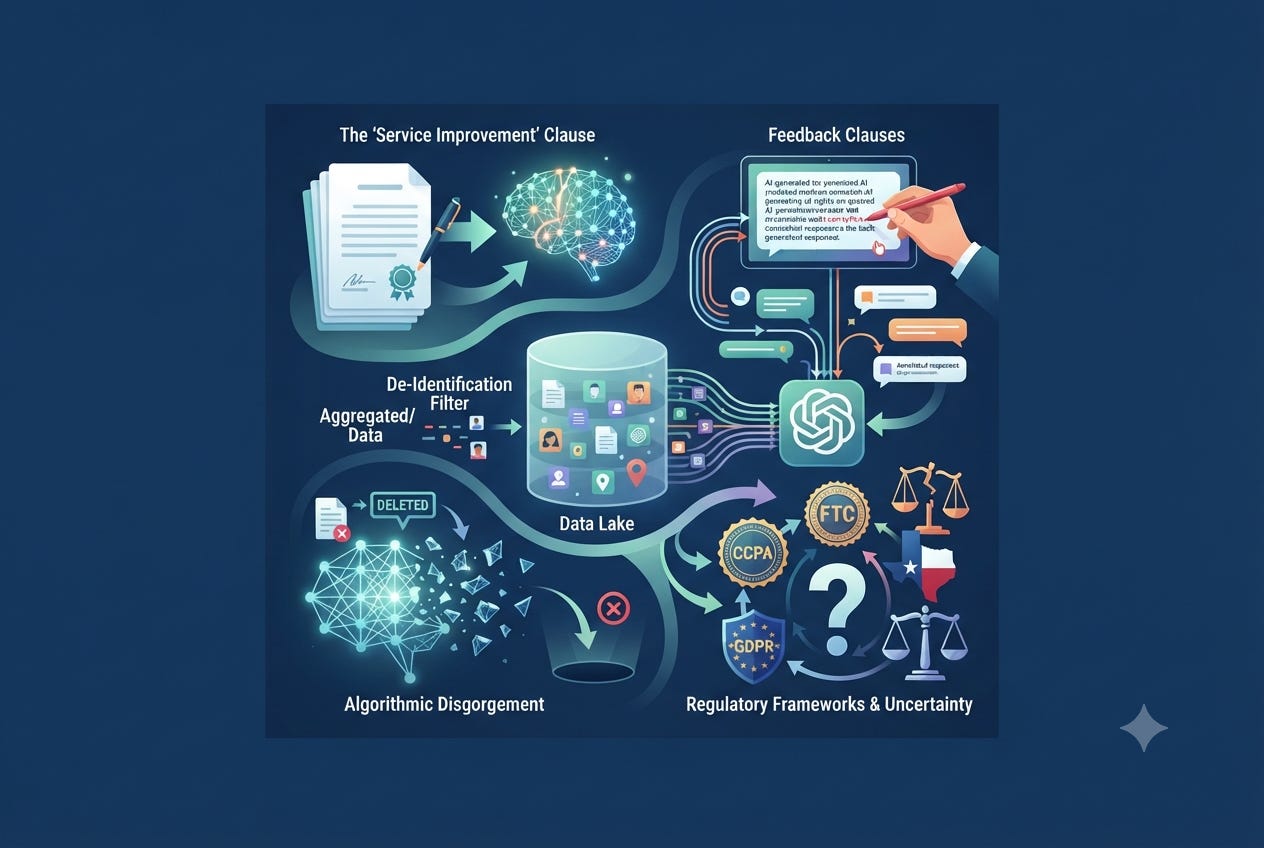
The Federal Trade Commission ordered a California photo app called Everalbum to delete the photographs it had collected and every facial recognition model it had built from those photographs, and it issued that order in January 2021, two years before most founders had heard the phrase generative AI. The remedy is called algorithmic disgorgement, and it is the clearest indicator regulators have given that a company cannot keep the output of improperly used data even after deleting the input. Everalbum had told users that facial recognition required their consent while running the feature by default for most accounts, then combined the resulting face data with public photo sets to build recognition technology it later sold. The Commission’s order reached past the photographs into the algorithm itself. That distinction, between deleting data and deleting what a company built from the data, is the one every startup with a five year old vendor agreement needs to understand right now.
Here is the part that should concern a founder more than the Everalbum case itself. Everalbum got caught because it lied about consent. Most startups have never lied to anyone. They signed a standard software as a service agreement, the kind every vendor sends, containing a clause granting the vendor the right to use customer data “to provide, maintain, and improve the services.” That clause has existed in software contracts for two decades, written for a world of bug fixes and uptime monitoring. Attorney Juanita DeLoach called it out directly in a March 2026 analysis: the phrase “to improve our services” is broad enough to cover AI training without ever using the words artificial intelligence or machine learning. A vendor does not need to amend that agreement to start training a model on the data it already has permission to use. It only needs to decide that model training counts as improving the service, and the clause the startup’s general counsel approved in 2019 already says yes.
Two more clauses do the rest of the work, and both hide in plain sight. The feedback clause grants the vendor a perpetual, worldwide, royalty free license to use any suggestion or correction a customer provides, language written originally so a vendor could implement a customer’s product idea without a later ownership fight. Applied to an AI feature, that same clause captures every correction a user makes to a generated draft, every refined prompt, every annotated response. A team correcting a vendor’s AI generated contract draft, trying only to fix that one document, may be handing the vendor a license to train on the correction for every other customer who uses the tool afterward, competitors included. The third clause, permitting the vendor to use “aggregated or de-identified data,” looks the safest and gets the least scrutiny in a contract review, which is exactly why vendors lean on it hardest. The European Data Protection Board addressed the technical claim behind that comfort directly in Opinion 28/2024, published in December 2024: a trained model is not automatically anonymous just because a de-identification step happened somewhere in the pipeline. The Board requires proof that it is very unlikely anyone could extract personal data from the model or reconstruct it through targeted queries, assessed case by case. A contractual promise to de-identify data before training does not, on its own, meet that bar, and the promise still functions as a license whether or not the underlying anonymization actually holds.
Zoom gave the market a live demonstration of what happens when this goes wrong in public. In March 2023 the company quietly added terms permitting it to train its own and third party AI models on customer audio, video, and chat content. Nobody noticed until August 2023, when the terms surfaced and set off a rapid revolt among Zoom’s own enterprise customers, the kind of company that reads its own vendor contracts closely. Zoom walked the language back within days, promising it would not train models on customer content without consent, though it never fully clarified what that meant for customers already bound by the original terms. Legal commentary at the time pointed to a real problem underneath the public relations scramble: bundling AI training consent together with the basic service the customer was already paying for violates the purpose limitation principle under the General Data Protection Regulation, and separately involves the ePrivacy Directive’s restriction on intercepting electronic communications. Zoom is a company with the resources and the incentive to fix its terms fast once the backlash hit. A startup’s own vendor, smaller and further from public scrutiny, has far less reason to move quickly if nobody is reading the contract closely enough to notice.
The largest AI vendors now make public promises narrower than their own boilerplate would otherwise allow. OpenAI states that data submitted through its API and through ChatGPT Enterprise is not used to train models by default. Microsoft states that its commercial data protection commitments for 365 Copilot mean customer content is not used to train the underlying foundation models. Salesforce says its Einstein Trust Layer keeps customer data out of the large language models it uses unless a customer separately agrees otherwise. Every one of those statements is a business decision the vendor made because enterprise customers demanded it and because the Zoom episode showed what happens when a company gets caught doing otherwise, not because a federal statute requires it. A founder relying on a vendor’s public trust page instead of the actual data use clause in the agreement the company’s own lawyer signed years ago has no enforceable right the moment that trust page changes, or the moment the founder moves to a product tier the promise does not cover.
Regulators are starting to build the backstop the contracts do not provide on their own. California’s rule requiring a service provider contract to specify business purposes “with sufficient particularity” already means a vendor cannot lean on a vague improvement clause if the contract’s stated purposes do not name AI training specifically. The California Privacy Protection Agency’s new automated decisionmaking technology rule, with a compliance date of January 1, 2027, goes further, listing the use of personal information to train automated decisionmaking or biometric technology as an activity that triggers a mandatory risk assessment, with the risk assessment obligation itself starting a year earlier. Texas enacted its own Responsible Artificial Intelligence Governance Act in 2025, effective January 1, 2026, adding a state layer that now sits on top of whatever the vendor’s contract says. None of this retroactively fixes an agreement signed in 2020. It only means a founder reviewing that agreement today has more reason than ever to read the data use clause as an AI license rather than as boilerplate, and to ask the vendor, in writing, whether it has trained or intends to train any model on the company’s data under the authority that clause already grants.
Interested in analysis about the intersection of tech, policy and the law? Check out my Substack channel.